Fushigi Crawler
A bot crawler carries a flag as a header
Recon
We got these files:
python
~/ctf/alpacahack/web/fushigi-crawler
❯ tree 11:33:05
.
├── bot
│ ├── Dockerfile
│ ├── index.js
│ ├── package.json
│ ├── package-lock.json
│ └── public
│ └── index.html
└── compose.yaml
3 directories, 6 filesLets check the index.js
jsx
import express from "express";
import rateLimit from "express-rate-limit";

const FLAG = process.env.FLAG ?? console.log("No flag") ?? process.exit(1);

const app = express();
app.use(express.json());
app.use(express.static("public"));
app.use("/api", rateLimit({ windowMs: 60 * 1000, max: 4, }));

app.post("/api/crawl-request", async (req, res) => {
  const url = req.body?.url;
  if (typeof url !== "string" || (!url.startsWith("http://") && !url.startsWith("https://")))
    return res.status(400).send("Invalid url");
  try {
    const r = await fetch(url, { headers: { FLAG }, signal: AbortSignal.timeout(5000) }); // !!
    if (!r.ok) return res.status(502).send("Fetch failed");
    return res.sendStatus(200);
  } catch (e) {
    return res.status(500).send(`Something wrong: ${e.name}`);
  }
});

app.listen(3333);
In this snippet:
jsx
  if (typeof url !== "string" || (!url.startsWith("http://") && !url.startsWith("https://")))
    return res.status(400).send("Invalid url");
The requirement input must be:
String
Starts with
http://orhttps://
Vulnerability
From this snippet:
python
const r = await fetch(url, { headers: { FLAG }, signal: AbortSignal.timeout(5000) }); // !!So the flag appears at the header when the bot fetching the URL.
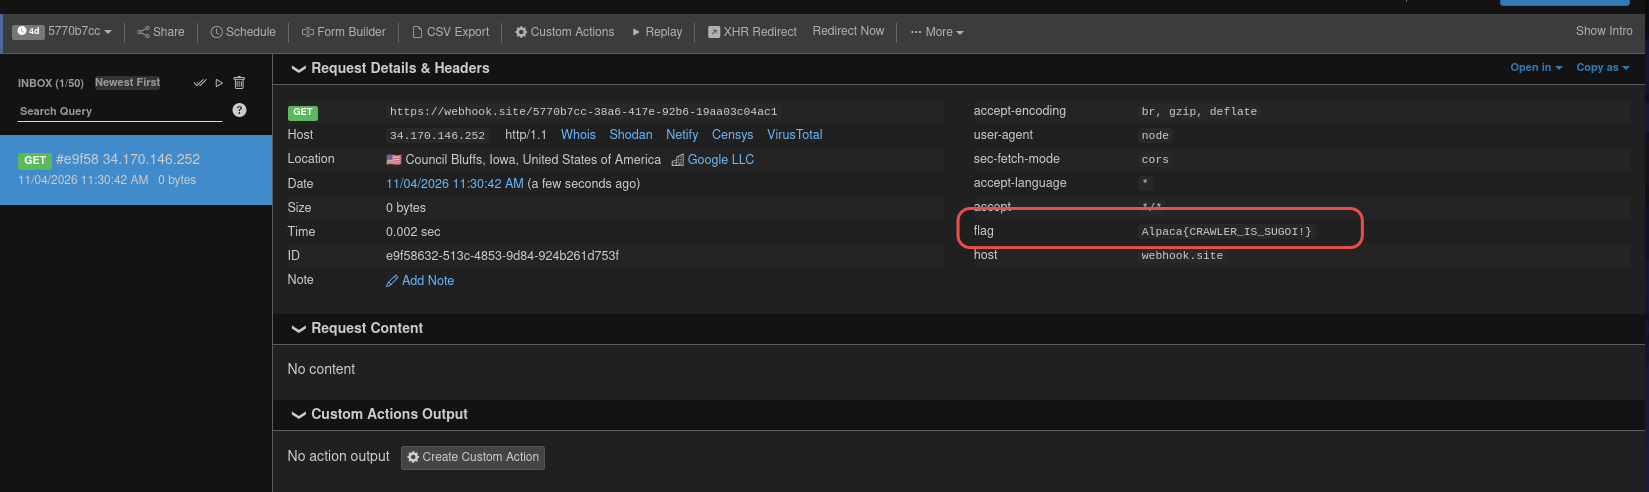
We can conclude so we have to setup a web so the bot will fetching to that URL with flag as a header. But we don’t bother to setup a web, there’s a website called webhook.site that we can use it for a temporary receiver that useful for receiving the fetch (GET)
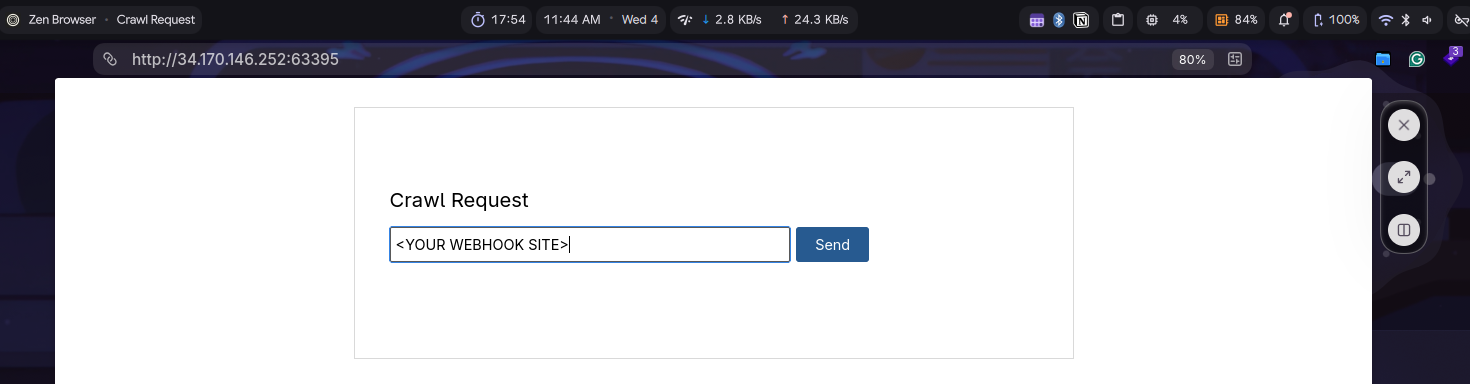
I tried it and then I successfully got the flag from the header.